Optimistic posterior sampling for reinforcement learning with few samples and tight guarantees
2022 · in (NeurIPS 2022)
Abstract
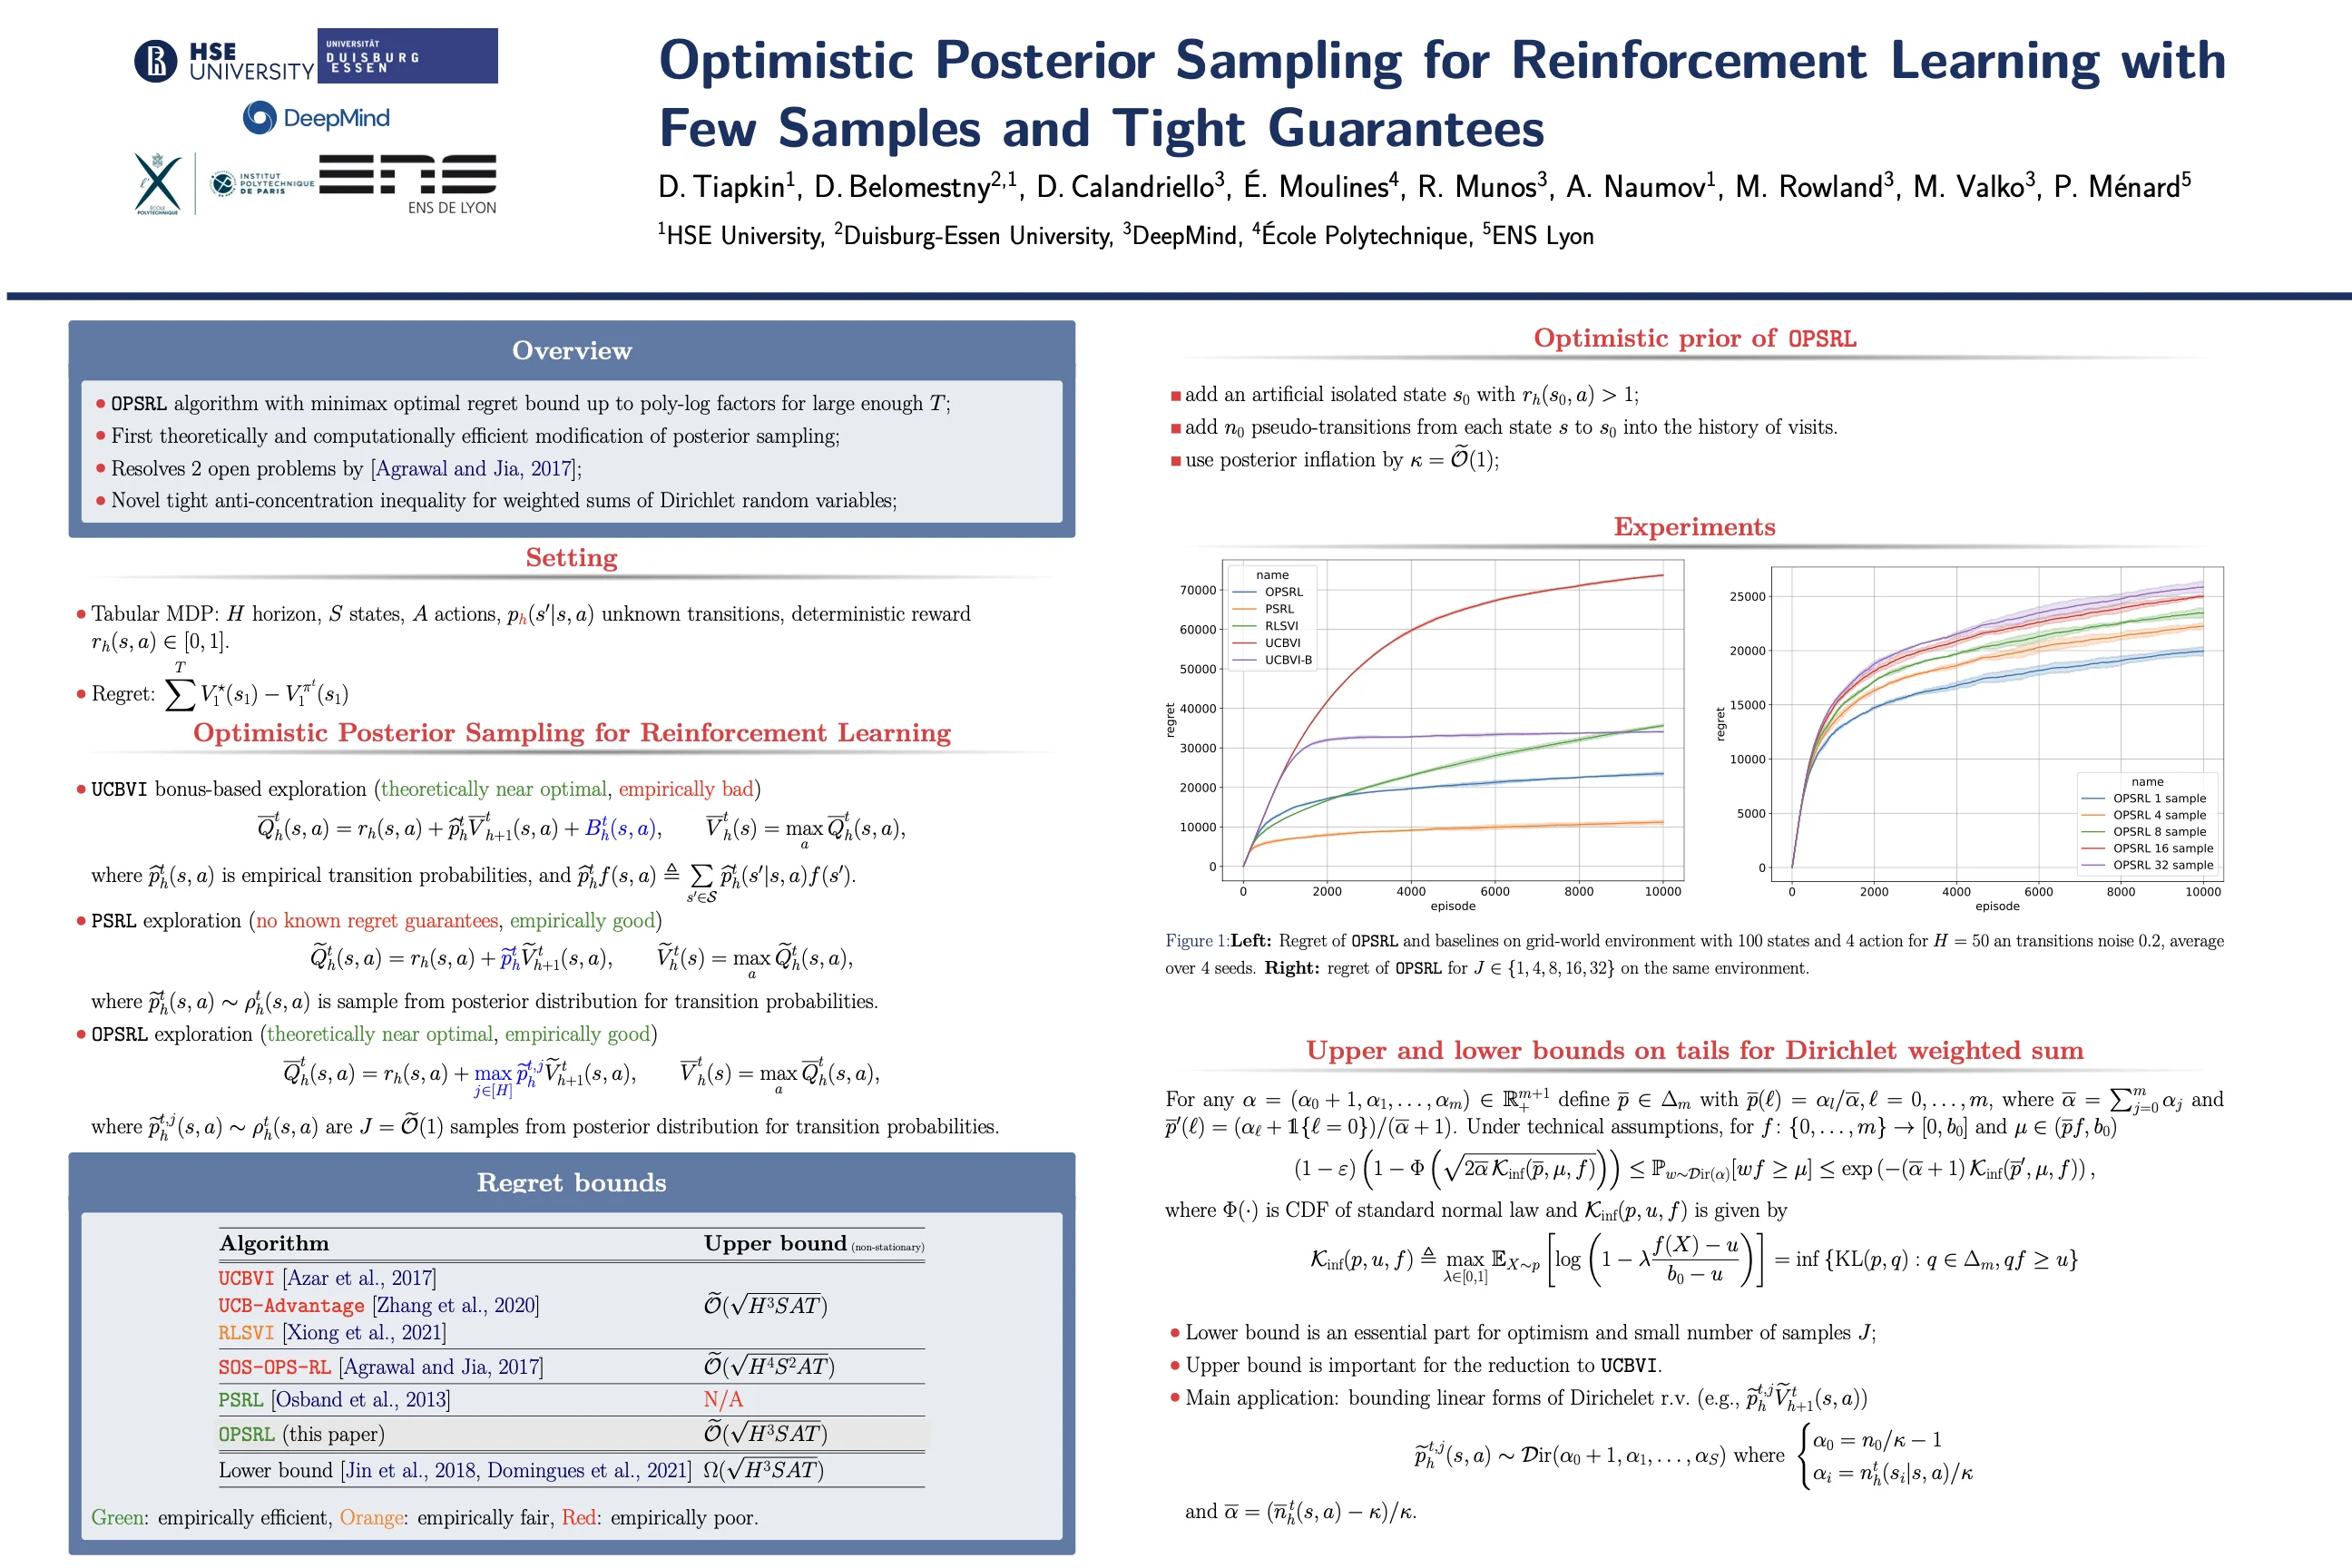
We consider reinforcement learning in an environment modeled by an episodic, finite, stage-dependent Markov decision process of horizon H with S states, and A actions. The performance of an agent is measured by the regret after interacting with the environment for T episodes. We propose an optimistic posterior sampling algorithm for reinforcement learning (OPSRL), a simple variant of posterior sampling that only needs a number of posterior samples logarithmic in H, S, A, and T per state-action pair. For OPSRL we guarantee a high-probability regret bound of order at most O(sqrt(H^3 SAT)) ignoring poly log(HSAT) terms. The key novel technical ingredient is a new sharp anti-concentration inequality for linear forms which may be of independent interest. Specifically, we extend the normal approximation-based lower bound for Beta distributions by Alfers and Dinges (1984) to Dirichlet distributions. Our bound matches the lower bound of order Omega(sqrt(H^3 SAT)), thereby answering the open problems raised by Agrawal and Jia (2017b) for the episodic setting.
PDF · Neural Information Processing Systems · arXiv preprint · poster · poster (image) · talk · bibtex · DOI